How Anweshna Scores Risk
Anweshna assigns every uploaded document a 0–100 score in each category of the ruleset that applies to it: 15 M&A risk categories by default, or a dedicated ruleset for banking (8 categories), pharma (7) or aviation (6). This page covers the M&A ruleset: where its categories come from, how they are weighted, what makes a category “blocking,” and — equally important — what the resulting score does not claim to establish.
What the score is, and what it is not
Anweshna performs document-level risk screening, not due diligence. A score reflects what the uploaded documents disclose and how that language reads against a defined rubric. It involves no independent verification, no primary research, no site visits, no management interviews, and no legal judgement. It does not replace counsel, an accountant's quality-of-earnings work, or a regulator's own review.
The intended use is triage: taking a data room too large to read sequentially and producing a ranked queue, so that human reviewers start with the documents most likely to contain material findings. Every output is designed to be checked, not trusted blindly — which is why findings carry the quoted source text they were derived from. To see what that looks like on a real filing, read the sample report further down this page.
Technology & Differentiation
Raw foundation models lack the precision required for institutional due diligence. Discover how our proprietary 7-layer pipeline strictly separates natural language understanding from deterministic risk scoring.
Accuracy & Benchmarks
Does the methodology work? We hold ourselves to a strict standard of independent validation. Our accuracy is measured continually against human-annotated real-world filings using an open benchmark.
Security & Compliance
Security isn't an afterthought — it's baked into the architecture from the ground up. Every client's documents and findings are encrypted at rest under a key derived uniquely for your engagement.
Our security program is aligned with leading frameworks such as SOC 2 and ISO 27001; we are planning formal certification as we scale.
The 15 M&A risk categories and their weights
Each category is scored independently on a 0–100 scale. The composite deal score is the weighted sum of the category scores; the weights below total 1.00.
| Category | Weight | Blocking |
|---|---|---|
| Financial | 0.18 | Yes |
| Legal | 0.13 | Yes |
| HR & Labour Compliance | 0.12 | Yes |
| Regulatory / Merger Control | 0.10 | Yes |
| Anti-Bribery, Sanctions & AML | 0.08 | Yes |
| AI & Tech Governance | 0.07 | Yes |
| Cybersecurity | 0.07 | — |
| IP & Licensing | 0.06 | Yes |
| Operational | 0.04 | — |
| Supply Chain & Geopolitical | 0.04 | — |
| Tax | 0.03 | — |
| Related Party | 0.03 | — |
| ESG & Environmental | 0.03 | — |
| Reputational | 0.01 | — |
| Data Privacy | 0.01 | — |
Weights encode deal-materiality, not frequency. Financial carries the largest weight because financial findings most often change price or kill a transaction outright; reputational carries the smallest because reputational signals in documents are typically corroborative rather than decisive. See the full category glossary for what each one screens for.
Blocking categories and the 70 threshold
Seven of the fifteen categories are blocking: Financial, Legal, HR & Labour, Regulatory / Merger Control, Anti-Bribery Sanctions & AML, AI & Tech Governance, and IP & Licensing. A score of 70 or above in any blocking category flags the deal for mandatory human review before it proceeds, regardless of how low the composite score is.
This is deliberate: a composite score can average away a single transaction-ending finding. A sanctions exposure does not become tolerable because the tax position is clean, so blocking categories are evaluated on their own terms rather than through the weighted total.
Absence of disclosure is not evidence of absence
Every blocking category carries a baseline floor on absence. If a document set contains no findings at all in a blocking category, that category does not score zero — it receives a small non-zero floor plus an explicit “no disclosure found” finding directing the reviewer to request the missing material. A silent data room is a diligence question, not a clean result.
Critical-phrase floors
Language models can soften genuinely severe findings. To stop that, a defined list of phrases forces a minimum score in the relevant category regardless of what the model itself assigned, in two tiers:
- Always-block phrases floor the category to 95. These are confirmed, terminal findings — an FCPA violation, a sanctions breach, an SDN-list match, a criminal investigation, an environmental remediation order, a going-concern qualification.
- Remaining critical phrases floor the category to 85. These indicate a serious but unresolved state rather than a confirmed outcome — for example a second request or Phase II merger review, which signals scrutiny rather than a decided result.
Floors are checked against negation. Explicit disclaimers (“no litigation pending”), hypothetical framing (“stress-test scenario”), and forward-looking diligence recommendations (“must be confirmed”) are detected so that a document stating a risk is absent is not scored as though the risk were present.
How sources are handled in our guides
The written guides on this site follow three rules, which are worth stating because they constrain what appears on the page:
- Statutory and regulatory figures are cited to primary sources — the United States Code, the Code of Federal Regulations, or the issuing agency — not to secondary summaries.
- Where a figure cannot be traced to a primary source, the figure is changed rather than the citation. Claims are softened to qualitative statements or removed. An approximate source is never attached to a precise claim.
- Ranges drawn from practice rather than statute are labelled as such. Timelines and cost bands reflect commonly observed patterns, vary substantially by transaction, and are not represented as authoritative.
Guides that cite statutory figures carry a Sources section listing those primary references. Thresholds and timelines change; verify current requirements with the relevant agency before relying on them.
Emerging risks outside the rubric
A fixed rubric cannot anticipate everything. On the deeper scanning tier, a separate detection pass looks for material risks that fall outside the defined categories and would not trip an existing critical-phrase trigger. These are logged as candidates for human review only.
A candidate never affects a score. It cannot change a category result, a composite score, or a blocking decision, and it never edits a ruleset automatically. Where a pattern recurs across several independent documents, it is clustered into a written proposal that a person must approve, after which any actual rule change is made through normal engineering review. Discovery proposes; humans decide.
Sample report: one real filing, screened
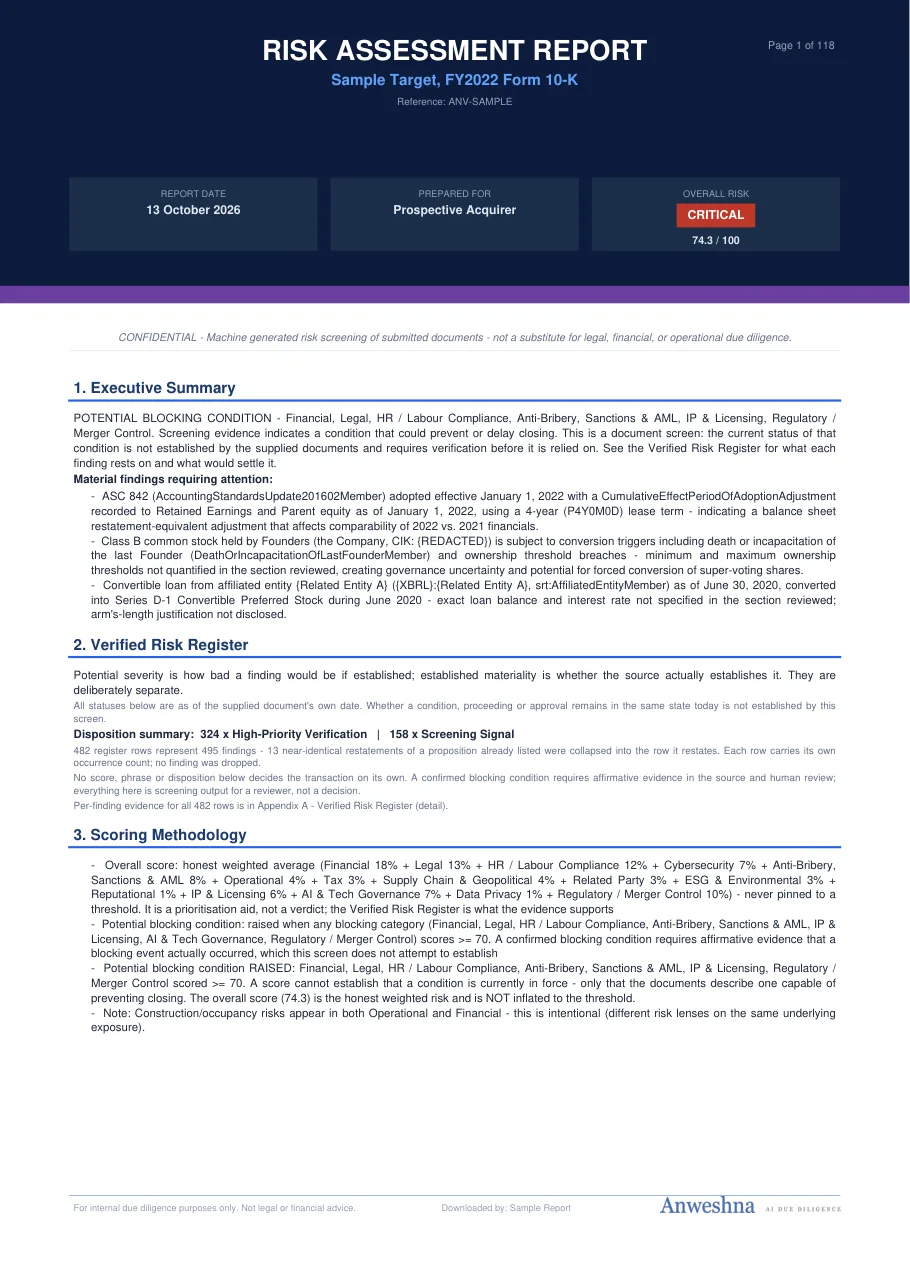
The rules above are easier to judge against real output. This is the full report Anweshna produced for one public annual report, a Form 10-K of about 88,000 words, with the company’s name and identifying details redacted. Nothing else in it was edited.
How this sample was made. The filing is a FY2022 Form 10-K filed with the SEC. Deep Scan scored it against the M&A ruleset on 31 August 2026. On 13 October 2026 those same findings were run back through the current evidence checks, second-stage verifier and report renderer, so the layout and every verification field reflect the engine as it is today. The company, its officers, related entities, auditors and case numbers are replaced with labels in braces, such as {Related Entity A}. The facts of the filing are unchanged, so a reader who knows the sector may recognise it.
This is screening output, not due diligence. The accuracy figures published on this site were measured on the single-pass Precision engine, so they don’t describe this Deep Scan report.
- Overall risk
- 74.3 / 100
- Shown as Critical because blocking categories crossed 70
- Blocking categories at 70+
- 6 of 7
- AI & Tech Governance is the seventh, at 50
- Findings
- 495
- 483 register rows after restatements are collapsed
- Dispositions
- 324 · 159
- High-priority verification · screening signal. None reached a blocking rung
- Verification plan
- 113 tasks
- Across 14 diligence workstreams
- Length
- 118 pages
- 34 pages of report, then the per-finding appendix
 Open the full report (PDF, 118 pages, 463 KB)
Reading it section by section
Every report has the same sections in the same order, whatever its export format. Here is what each one tells you, and what it says in this sample.
| Section | Pages | What it tells you | In this report |
|---|---|---|---|
| Cover | 1 | Overall score and rating. The rating reads Critical only when a blocking category has crossed 70. | 74.3 / 100, Critical. |
| 1. Executive Summary | 1 | The headline disposition, and the most severe findings from the highest-scoring categories. | “Potential blocking condition”, naming six categories. Potential, because a score crossing 70 doesn’t establish that a block has occurred. |
| 2. Verified Risk Register | 1 | What the evidence supports: how many findings sit on each rung of the disposition ladder, and how many restatements were folded together. | 324 high-priority verification, 159 screening signal. 495 findings make 483 rows. |
| 3. Scoring Methodology | 1 | The weight formula and which blocking categories tripped, so the headline number can be checked by hand. | The weights in the table above reproduce the score: 74.33 against 74.3 reported. |
| 4. Risk Category Breakdown | 2 | Score, severity and most severe finding for each of the 15 categories. “Most severe” is picked by severity tag, not by how much it moved the score. | Financial 95 and Legal 92 lead. The full table is below. |
| 5. Detailed Findings | 2–28 | Every finding, grouped by category, with tags for severity and for what the verifier found. | 495 findings. |
| 6. Recommended Next Steps | 29 | Diligence requests drawn from the categories that triggered. | 9 steps, for example “Engage CFIUS counsel; assess national-security review timeline and mitigation-agreement exposure before proceeding.” |
| 7. Verification Plan | 29–33 | Concrete tasks grouped by the workstream that would do them, most urgent first. Identical instructions are merged and counted. | 113 tasks across 14 workstreams. None is P1, the priority reserved for a blocking-rung finding whose evidence is missing. |
| 8. Limitations | 34 | Scope, method and the ruleset the document was scored against. | Single-document screen, M&A ruleset, 15 categories. |
| Appendix A | 35–118 | One entry per register row: the full verifier record behind each finding. | 483 entries. One is broken down field by field below. |
One register entry, field by field
This is a single entry from Appendix A, exactly as printed. Every finding in the report carries the same fields.
Financial
Auditor {Successor Auditor} issued an ADVERSE OPINION on the Company’s internal control over financial reporting as of December 31, 2022, based on COSO Internal Control—Integrated Framework (2013), dated September 7, 2023.
| Field | This entry | What it means |
|---|---|---|
| Evidence type | Actual event | The filing reports something that happened. Other types include management risk factor, model inference, live regulatory action and diligence gap. |
| Source support | Partial (100%) | How closely a passage located in the filing states the same thing: direct, partial, indirect, unsupported or contradicted. The percentage is the evidence confidence; the confidence basis below says what it rests on. |
| Potential severity | Medium | How serious the finding would be if it is established. |
| Established materiality | Potentially material | Whether the filing itself establishes that it matters. Kept separate from severity on purpose. |
| Deal specificity | Medium | How closely the finding is tied to this transaction rather than to the business in general. |
| Transaction impact | Unknown | Which part of a deal it touches, such as valuation or closing. Unknown means the filing doesn’t say. |
| Disposition | High-priority verification | Its rung on the ladder: screening signal, high-priority verification, potential blocking condition, confirmed blocking condition. |
| Why not higher | “Human verification is required before materiality or blocking status can be established.” | Which gate held the finding on its rung. |
| Question for review | “What was the outcome of this event, and what exposure survives to the buyer?” | The question a reviewer should answer before relying on it. |
| Review reasons | “A past event; whether it is still outstanding is not established.” | Why the entry needs a person, in plain words. |
| Confidence basis | Text overlap 100%; passage match 75% | What the confidence figure rests on, rather than a bare number. |
| To verify | “Obtain the underlying record… and establish scope, quantum and current status.” | The evidence that would settle it. These feed the Verification Plan. |
Category scores in this report
| Category | Score | Severity | Blocking |
|---|---|---|---|
| Financial | 95 | Critical | Yes |
| Legal | 92 | Critical | Yes |
| Related Party | 88 | Critical | — |
| Operational | 85 | Critical | — |
| Reputational | 85 | Critical | — |
| HR & Labour Compliance | 72 | Critical | Yes |
| IP & Licensing | 72 | Critical | Yes |
| Regulatory / Merger Control | 72 | Critical | Yes |
| Anti-Bribery, Sanctions & AML | 70 | Critical | Yes |
| Cybersecurity | 62 | High | — |
| Supply Chain & Geopolitical | 58 | High | — |
| AI & Tech Governance | 50 | Medium | Yes |
| Tax | 45 | Medium | — |
| Data Privacy | 45 | Medium | — |
| ESG & Environmental | 22 | Medium | — |
What this report does not tell you
- No single finding reached a blocking rung. The headline says potential blocking condition because six blocking category scores crossed 70. The per-finding ladder found no entry with affirmative evidence of an actual blocking event. The report prints both, and neither is a verdict.
- The headline names blocking categories only. Related Party, Operational and Reputational score 85 or more but aren’t blocking, so the executive summary doesn’t name them. Read the category table, not just the headline.
- Unsupported findings stay in, marked. For 173 of 495 findings the verifier located no passage stating the same thing, and for 35 the passage it found says the opposite. Those findings are labelled in the register, not dropped.
- A few findings quote XBRL element names, such as AccountingStandardsUpdate201602Member, because the August run saw the filing’s machine-readable XBRL header. That header is now removed before scoring. The findings are printed as the model wrote them, not tidied after the fact.
How we measure accuracy
Scoring claims are worth what the evidence behind them is worth, so this section describes how accuracy is measured here — and what the published figures do and do not support. The sample is small and the intervals around it are wide, so both are reported alongside every number rather than behind it.
The ground truth is public
Measurement runs against real annual reports filed with the U.S. Securities and Exchange Commission, retrieved from EDGAR. These are public, free to re-fetch, and redistributable, which means anyone can pull the same filing and check our work. A benchmark built on documents nobody else can see is a marketing claim, not a benchmark.
Each filing is pinned by a cryptographic hash of its extracted text. If the text changes, the measurement refuses to run rather than quietly scoring a different revision against annotations written for the original.
What is labelled, and what is deliberately not
For each filing, a reviewer records which risk categories a competent reader would refuse to close without resolving, and which they read and found clean. Three rules constrain that labelling:
- Only categories actually checked are labelled. Anything unlabelled is excluded from the arithmetic entirely rather than counted as a clean result. Treating "not examined" as "nothing found" would manufacture correct answers by the hundred and inflate any accuracy figure for free.
- A category is called clean only on positive grounds — an explicit disclosure that nothing material exists, or a section read and found clear. "I did not look" is not the same as "there is nothing there."
- Every annotation quote must appear verbatim in the filing. A paraphrased annotation becomes a target that cannot be found, which the scoring engine is then blamed for missing.
Where a reviewer is unsure, the category is left unlabelled. An honest gap makes the sample smaller; a guess makes it wrong.
Measured against the decision, not the number
Accuracy is measured against the flag — whether a category crossed the review threshold — not against the composite score. That is the decision a deal team actually acts on, and the only one a reviewer can label without inventing a numeric ground truth.
Detection of specific transaction-critical findings is measured separately. For each filing, the individual disclosures a deal team would stop on are recorded by name, and whether each was surfaced is tracked independently of the category flag. A report can trip the right category while missing one of the reasons it should have.
Filings are chosen in matched pairs. For any given signal, the sample holds both a filing where it is genuinely present and one where the same vocabulary appears as routine legal boilerplate. A system can score perfectly on either alone by being uniformly cautious or uniformly alarmed; only the pair distinguishes judgement from bias.
Evidence checks are reported in three parts, not one
Every finding is checked against the source document. Findings are sorted into those whose quoted text and figures were located, those carrying something checkable that could not be located, and those offering nothing checkable at all. The second and third are reported separately because they mean different things: unsupported is not the same as contradicted.
The proportion that fails an automated check is not a hallucination rate and will never be published as one. It is an upper bound. Known causes flag correct findings — for example, a finding that restates two figures from a document and computes the difference states a number that is legitimately absent from the source. A genuine hallucination rate requires reading the flagged findings individually, and we have not finished doing that.
Current status
The annotated sample covers thirty filings — the target it was set — and every one of the fifteen risk categories carries at least one label. Thirteen of the fifteen are matched in both directions; two are represented in one direction only, because the filing needed for the opposite case is genuinely hard to find rather than merely unwritten.
Results are published: 94.1% precision and 84.2% recall on the deal-blocking gate, measured across twenty of those filings and thirty-five labelled category-cases. The commitment made here before the numbers were known has been kept — the categories the system scores worst and the one transaction-critical finding it failed to surface are named individually, alongside the sample size and the confidence intervals. The labels remain the work of a single reviewer, which is a real limit on what the numbers carry. Full results are on the Accuracy & Benchmarks page.
Known limitations
- Scanned documents without a text layer cannot be scored. Pre-flight checks reject unreadable files rather than scoring them as clean.
- Very large documents are chunked, and where a document exceeds the single-pass window it is either routed to the chunked engine or, with explicit consent, truncated — in which case the stored report is marked as truncated.
- Scores are not comparable across different rulesets. A 62 under the banking ruleset does not mean the same thing as a 62 under the general M&A ruleset.
- The system reads what it is given. It cannot detect what a seller chose not to place in the data room, which is precisely why absent disclosure in a blocking category raises a flag rather than passing silently.